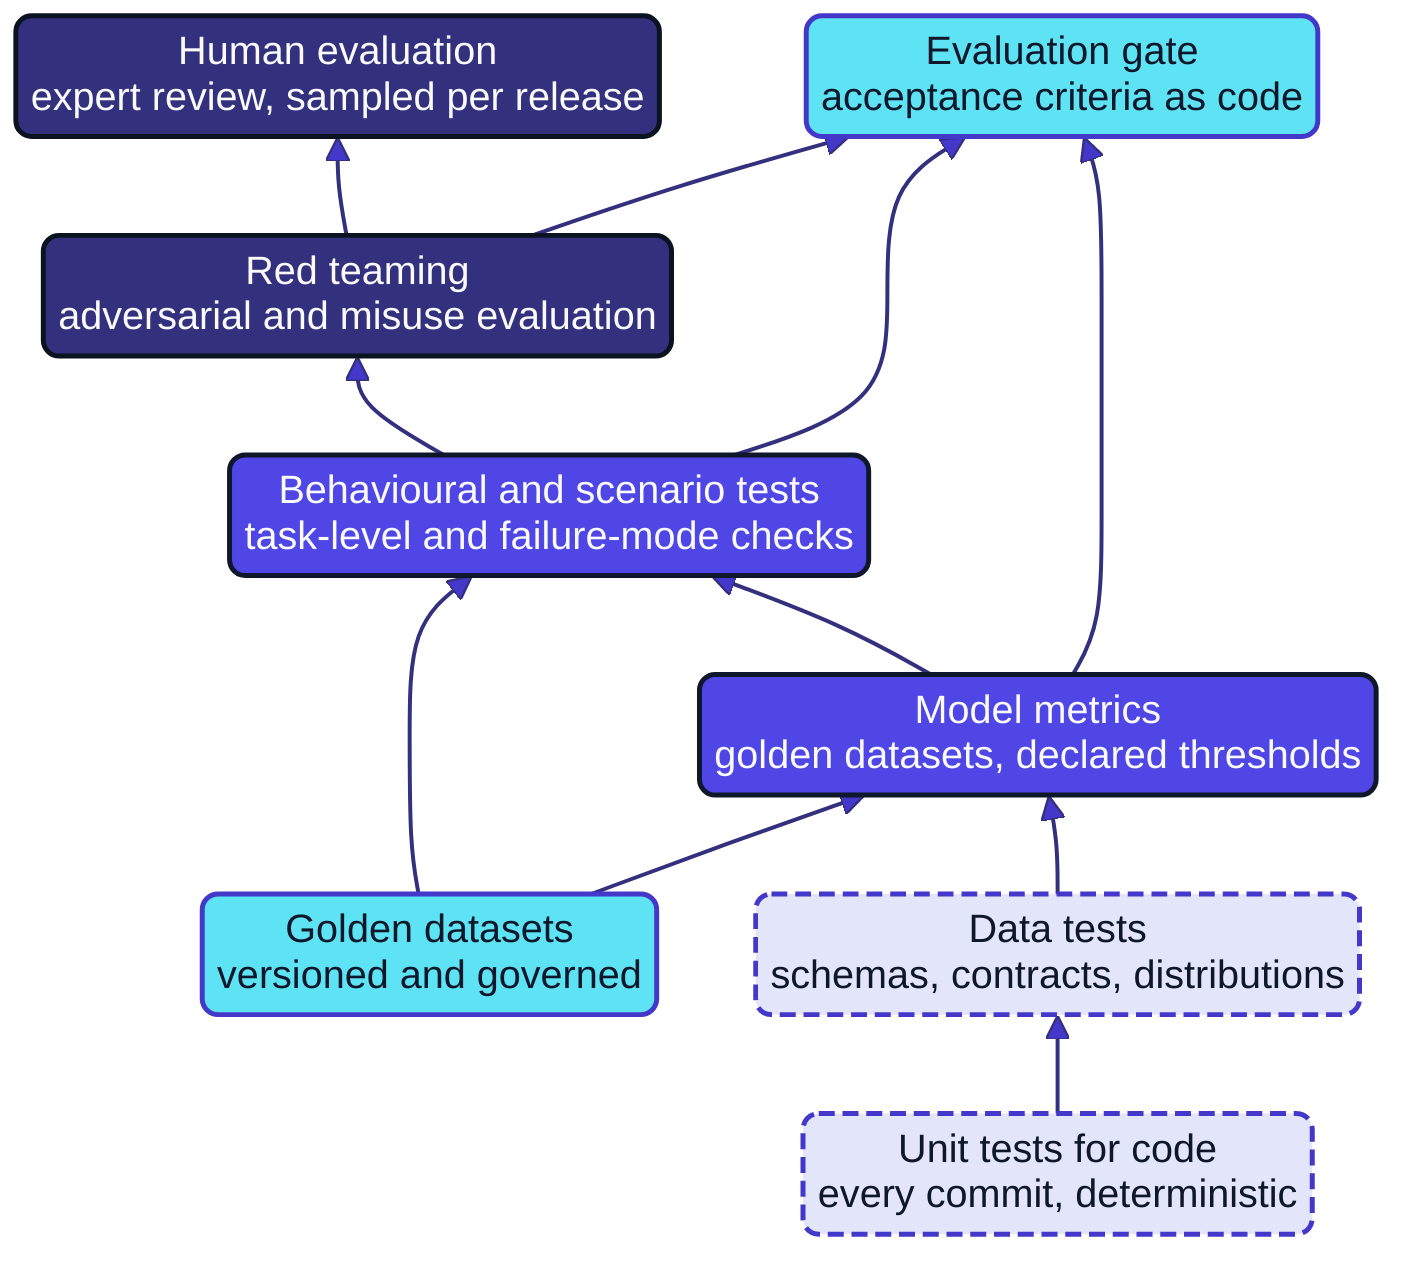
This chapter opens Part V, on delivery and operations, and defines a testing strategy for systems whose most important component behaves probabilistically. It builds on the testing discipline of Architecture as Code (Chapter 13) (72, Nordqvist, 2025), where tests are version-controlled artefacts that run on every change, and extends it with the layers models require: data tests, model metrics against golden datasets, behavioural tests, red teaming and human evaluation. It connects the strategy to Articles 9, 15 and 55 of Regulation (EU) 2024/1689, the AI Act (1, European Union, 2024).
A unit test asserts that a function returns a specific value for a specific input, an assertion that is meaningless for a classifier whose accuracy is a statistical property of a population, or for an LLM whose output varies between runs. The ML Test Score of Breck et al., which Chapter 7 uses as a readiness gate, spread its tests across data, model development, infrastructure and monitoring, and scored the weakest area (66, Breck et al., 2017). Its structure survives the shift to foundation models; only the content of the model development and monitoring areas changes.
Evaluation therefore runs continuously, from before training to production, and its datasets, suite definitions, thresholds and reports belong in version control next to the model. AI Governance, Chapter 11 binds the artefacts of each release into a signed evidence manifest in which the evaluation report is the most important piece of evidence, and Chapter 21 depends on it too, because production should monitor the metrics the release was accepted on.
Primary topics explored
- Why probabilistic systems need a different testing strategy
- The evaluation pyramid
- Golden datasets and their governance
- Composition
- Contamination and personal data
- Known limitations
About AI Platform and Security
AI Platform and Security is Book 3 of The Transformed Architecture. It shows how large European enterprises and public authorities build, secure and operate the platform on which artificial intelligence runs: data, models and DevSecMLOps, retrieval and agents, infrastructure and sovereignty, AI security engineering, evaluation, observability and cost.
The companion volume AI Governance covers risk management, governance, assurance, organisation and leadership; Architecture as Code supplies the underlying discipline.
Platform engineers, security architects, MLOps teams, AI architects and technical decision-makers.

Gunnar Nordqvist
Conceived, directed and published the books of The Transformed Architecture.
Continue with the full chapter
Chapter 20: Evaluation and Testing of AI Systems in AI Platform and Security gives the detailed explanations, practical examples and implementation patterns behind this summary.
This whitepaper belongs to “Delivery and Operations” and is one of 29 drawn from the manuscript.